How to design a calibration session that does not turn into a negotiation over scores
How do you keep a calibration session from turning into a negotiation over scores? Bring evidence, context, and criteria into the conversation before the number.
Consider a leader who argues for a four while another believes the case deserves a three. The conversation continues for twenty minutes and ends at 3.5. No one could explain which evidence changed or what the intermediate number means.
The session produced numerical agreement, but not calibration.
Calibration should increase the consistency with which criteria are interpreted in comparable situations. It neither requires everyone to reach the same judgment nor eliminates uncertainty. It requires differences to be open to examination and the conclusion to retain a reconstructable basis.
Prepare cases, not positions
Before the meeting, select decisions that genuinely need review: cases with significant consequences, wide discrepancies, or evidence that is difficult to interpret. Do not bring every assessment into the shared forum.
For each case, prepare a short brief containing the context, the applicable expectation, the observations available, and their sources. Separate facts, interpretation, and the provisional conclusion.
Do not include personal information that is unnecessary for the purpose. Calibration does not improve by accumulating details, and excess information increases bias and confidentiality risks.
The OPM describes performance management as a cycle that includes planning, monitoring, developing, rating, and rewarding; it also emphasizes that the process is broader than assigning ratings. The framework belongs to US federal employment, but it reinforces a general precaution: a final number depends on expectations and prior observations. U.S. Office of Personnel Management, Performance Management Cycle (opens in a new tab).
Begin with the evidence and the rule
The person presenting the case should answer in this order:
- What was expected in that situation?
- What happened, and how do we know?
- Which part of the expectation is supported?
- What information is missing?
- Which decision will use the conclusion?
The score comes later. This sequence prevents the discussion from becoming a defense of the previous rating from the outset.
The facilitator should ask for observable language. “They show great leadership” is a judgment. “During an outage, they coordinated three functions, stated the priority criterion explicitly, and revisited the decision when new evidence emerged” provides elements that can be compared.
Classify the disagreement before resolving it
Not every discrepancy means that someone applied the scale incorrectly. Disagreement can have at least four sources.
There is disagreement about facts when people know about different episodes. The response is to gather or delimit evidence, not average memories.
There is disagreement about the criterion when a definition allows incompatible readings. The case may expose a rule that the architecture needs to clarify.
There is disagreement about context when the same action involved different levels of complexity, autonomy, or risk. The conversation must reconstruct those conditions.
There is disagreement about sufficiency when everyone accepts what was observed but differs on how much can be concluded from it. Here, it is better to preserve the limits and decide what additional evidence would be reasonable to obtain.
Labeling the type of discrepancy reduces circular arguments. It also produces input for improving definitions and guidance.
Protect states that are not scores
If someone had no reasonable opportunity to act in a situation, the session cannot invent performance. If the skill is not relevant to the role’s purpose, the problem may lie in the architecture. If signals conflict, the conclusion may remain open.
Well-documented uncertainty is more useful than fictional precision. It allows the organization to decide whether it needs further observation, an adjustment to the instrument, or a limit on how the result may be used.
Close with a reconstructable conclusion
The record does not need to transcribe the entire conversation. It should retain the expectation applied, the decisive evidence, the relevant objections, the final state, and the authorized use.
If a score changed, record which interpretation or evidence justified the change. If there was no conclusion, state what is missing and who will decide whether obtaining it is worthwhile.
The OPM’s roadmap for supervisors places assessment within a continuous performance-management process. Although it does not prescribe this session, it reminds us that calibration should not be an isolated event that repairs expectations at the end that were never agreed on in the first place. U.S. Office of Personnel Management, Performance Management Roadmap for Supervisors (opens in a new tab).
Review the system after reviewing people
If many cases raise the same question, do not conclude that every leader needs more training. Perhaps the scale conflates autonomy with complexity, the examples represent only one context, or the architecture places an expectation in the wrong role.
Record patterns without using calibration as a disciplinary mechanism. The systemic objective is to learn where assessment loses clarity.
This guide continues What it means for an assessment to be valid for a specific decision and Not observed, not applicable, and insufficient evidence do not mean the same thing. The quality of the session depends on preserving those distinctions when there is pressure to settle on a number.
A good calibration may end with different scores, an open case, or a rule that needs correction. Its success lies not in eliminating every difference, but in producing decisions that are more explainable than those that entered the room.
To extend this reading, see Self-assessment, manager, or peers — what each source contributes, which develops a complementary dimension of the problem.
Keep exploring
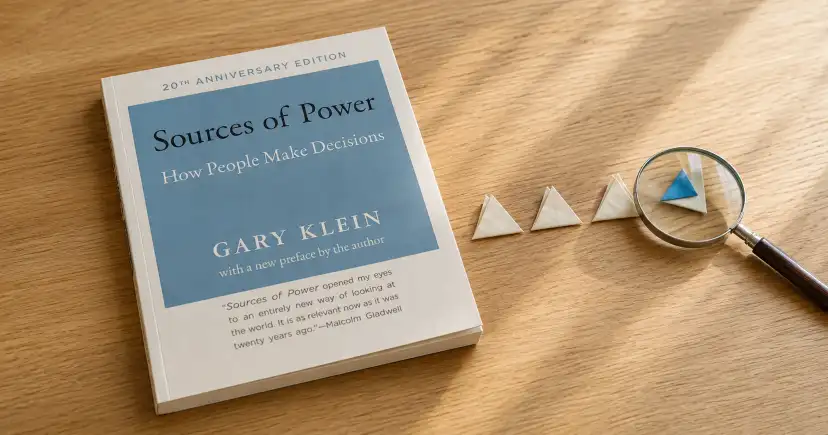
Sources of Power: when expert intuition deserves a place in assessment
Sources of Power makes it possible to treat expert intuition as situated recognition without turning experience or confidence into unquestionable authority.
How to add a 360 without turning it into an average
A 360 improves an assessment when it preserves what each source observed, from which relationship, and within what limits; averaging first destroys that information.
Bias and fairness: the same scale does not guarantee the same opportunity to demonstrate
An uncomfortable finding in assessment is that a common scale does not produce fairness when people lack comparable opportunities to generate and present evidence.
How to adapt an assessment without changing what it is meant to measure
Two people may demonstrate a capability in different ways while still meeting the same core demand. Fair adaptation requires separating the construct from barriers created by the format.
Who can see what: access, privacy, and purpose in talent data
Who needs to see a piece of talent data, in how much detail, and for how long? The answer begins with the authorized task, not hierarchical rank.
How long does a skills assessment remain current
An older assessment may still guide development yet be insufficient for assigning a critical responsibility. Its date alone does not determine whether it remains useful.